AI RequirementsEngineering Platform.
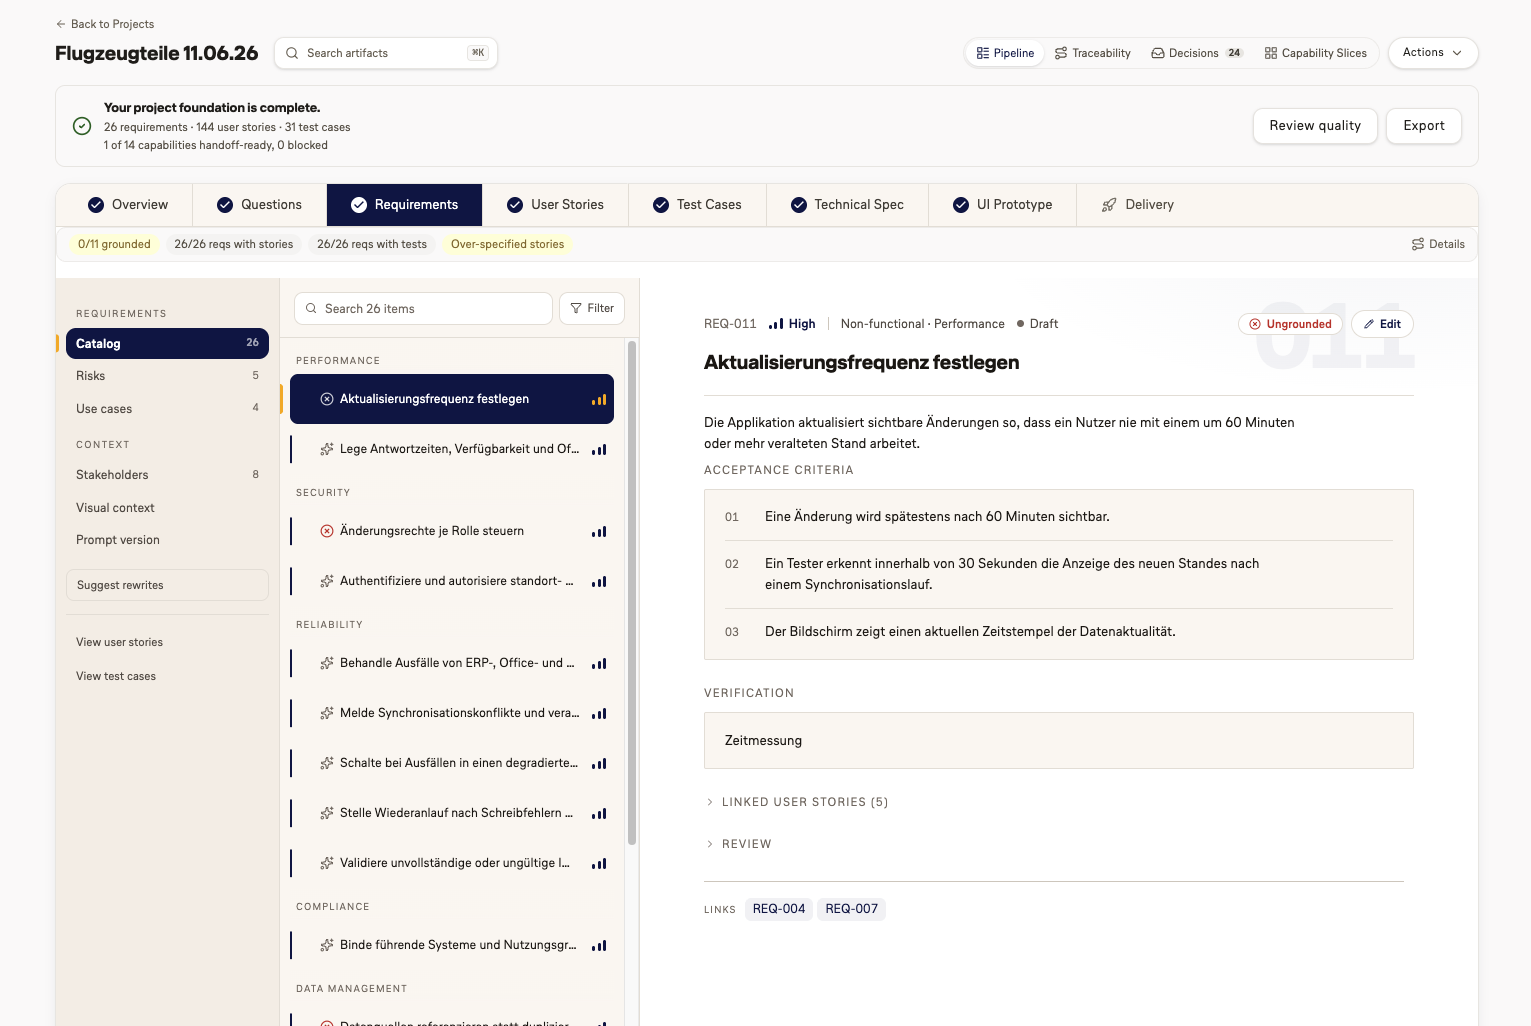
An enterprise platform that turns sparse customer input — notes, questionnaires and RFP material — into a traceable project specification: requirements, epics, user stories, test cases and technical specifications. The difficult part is not generating text; it is preserving structure, provenance and quality across a long-running multi-stage pipeline.
- Next.js
- React
- TypeScript
- Express
- BullMQ
- Azure OpenAI
- Cosmos DB
- Elasticsearch
- Redis
- Azure Container Apps
What I built
- A staged generation pipeline. Raw input becomes requirements first, then epics and stories, then tests and technical specifications. Dependencies are sequential where context matters and parallel where artifacts can be generated independently.
- Structured model output. Zod-validated contracts turn model responses into typed application data rather than loosely parsed prose.
- Grounding and traceability. Hybrid Elasticsearch retrieval combines keyword precision with dense-vector recall so generated items can carry evidence back to source material.
- Quality and refinement loops. Low-scoring artifacts can be regenerated or expanded rather than silently accepted.
- Long-running job architecture. API traffic and generation workers are separate processes so multi-minute AI jobs do not block the normal application surface.
- Evaluation infrastructure. Pipeline changes can be compared against a reference corpus using structural coverage, semantic similarity, citation correctness and hallucination-oriented checks.
How the product evolved
Process reconstruction — based on the architecture, implementation history and current system shape. It describes the design trajectory rather than claiming every decision happened in one documented meeting.
The first useful milestone was proving that sparse input could produce structured requirements at all. At that point, output quality was still evaluated mostly by inspection.
Requirements, epics, stories and tests stopped being parallel “AI features” and became a directed pipeline. Downstream artifacts inherit context instead of independently hallucinating the same project.
Once the output became useful enough to act on, “where did this come from?” became a product requirement. Retrieval and citations moved from enhancement to core system behavior.
Generation jobs can take minutes. Moving them into worker queues turned progress, retries, checkpoints and recovery into explicit product states instead of HTTP timeout edge cases.
Prompt changes that looked better in one demo could regress another domain. A reference-corpus evaluation layer became necessary to make iteration measurable.
Architecture
UI / interaction rationale
Key engineering decisions
- Hybrid retrieval instead of a separate vector-only database. Requirements work needs exact terminology and semantic recall, so BM25 and embeddings are fused rather than choosing one.
- Decoder-level schema constraints instead of prompt-only JSON instructions. Invalid structure is an application failure mode, not a stylistic issue.
- Optimistic concurrency instead of naive last-write-wins. Independent workers can finish at almost the same time and must not overwrite each other silently.
- Checkpointed generation instead of all-or-nothing runs. Expensive multi-stage work should resume from a stable stage after failure.
- Evaluation before scaling prompt complexity. Once a pipeline has many stages, human spot checks are not enough to understand regressions.
Challenges & lessons
- Schema drift is deterministic failure disguised as an AI problem. If the prompt asks for a field the application schema does not accept, retries cannot fix the mismatch. Contract tests are more valuable than another retry loop.
- Two-process systems need an explicit event story. An in-process event emitter cannot magically cross from a worker container to the API process; progress requires shared messaging or a resilient polling fallback.
- Completeness competes with cost and latency. “Generate everything” is not free. The useful control is budget-aware generation and staged depth, not arbitrary hard caps that truncate the specification.
- Evaluation should have existed earlier. Without a reference corpus, prompt iteration stays subjective for too long and local improvements can hide system-level regressions.
Case-study boundary
This page intentionally describes the system pattern rather than exposing customer-specific data, internal names or proprietary process details. The architectural lessons are the portfolio evidence; confidential domain content is not.